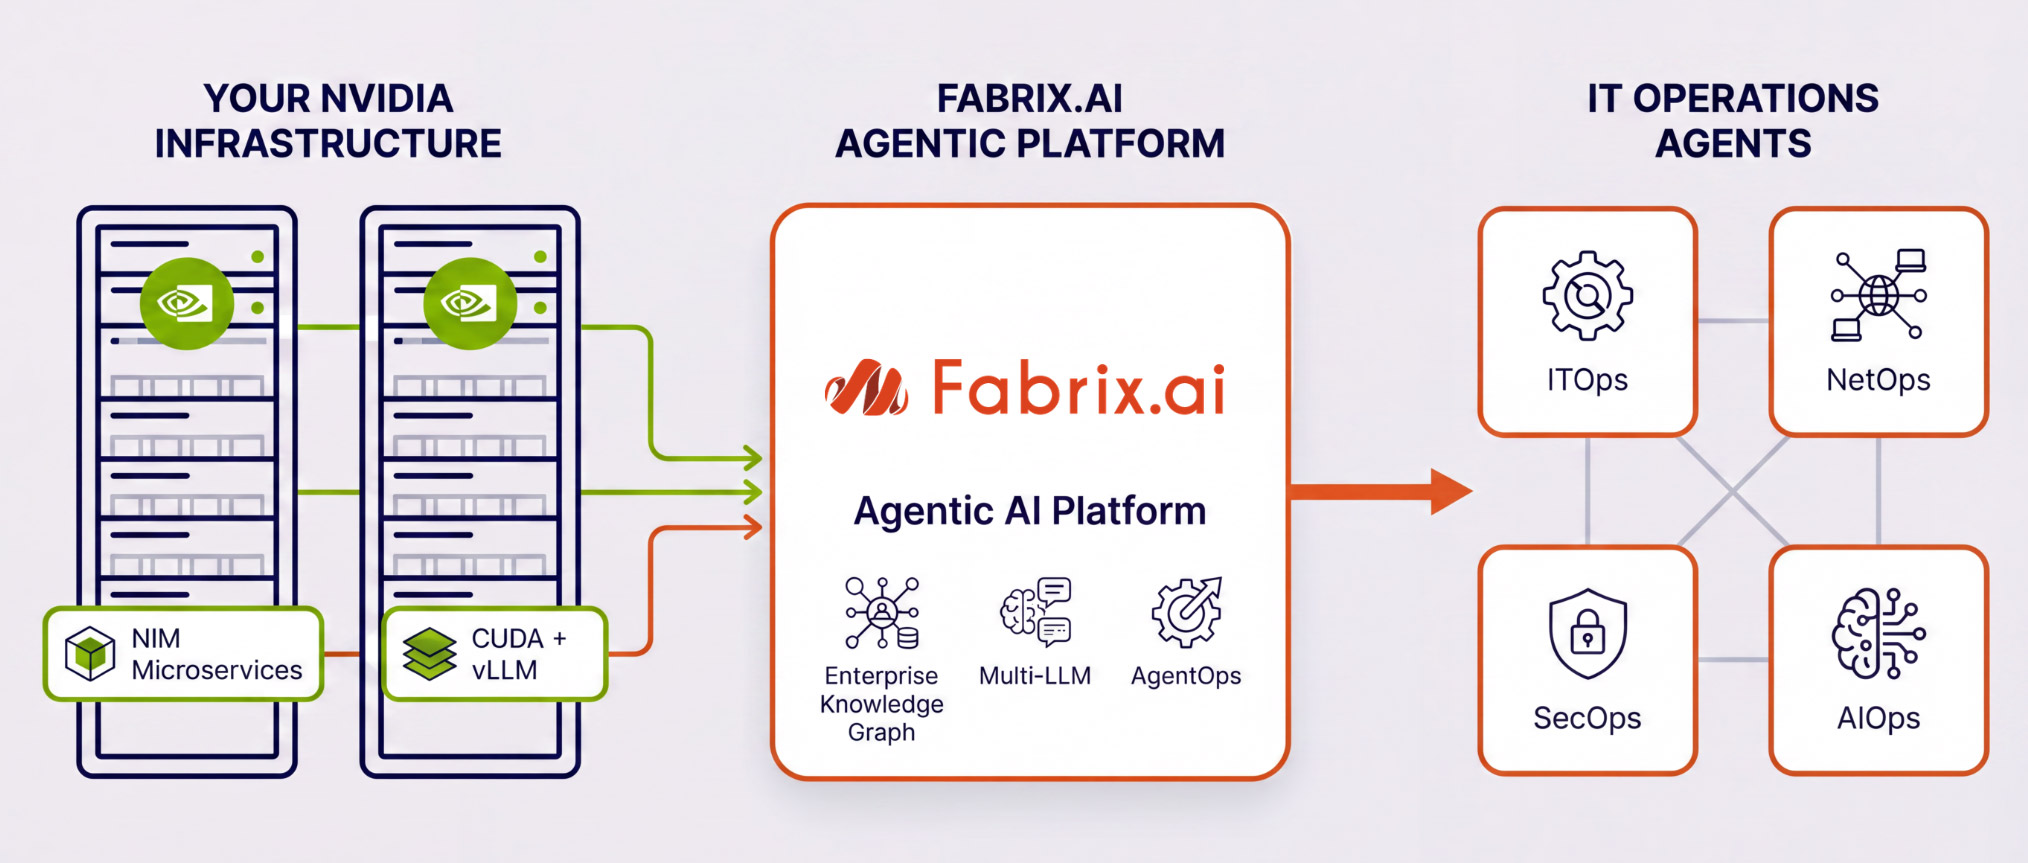
Path A: NVIDIA NIM
With NVIDIA NIM Microservices
- Fully managed
- Enterprise SLA
- Latency-critical
- NVIDIA-first stack
- 2
Deploy Nemotron, Llama, Mistral, or any supported model as a NIM container on your NVIDIA GPU servers. NIM handles drivers, optimization, and exposes a standard API endpoint.
- 3
Configure the NIM endpoint in Fabrix.ai's Multi-LLM settings. Fabrix.ai agents immediately begin using that model for investigation, reasoning, and action across your entire IT estate.
Ideal for enterprises prioritising a fully managed, optimised inference stack with NVIDIA enterprise support and guaranteed SLAs.